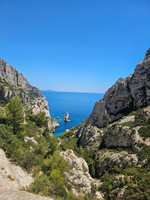
I was invited to give a talk at Learning and Optimization in Luminy (LOL), a week-long workshop at CIRM gathering young researchers and experts around generative modelling, optimization for deep learning and trustworthy machine learning. My talk, Optimizing Performative Learning, introduced the performative learning setting and covered my two papers on the topic: Optimal Classification under Performative Distribution Shift and Optimal Regularization for Performative Learning.
Back in Luminy four years after my first visit, with the same view on the Calanques.